
The user-facing service
Measures: latency, traffic, errors and saturation.
Source: Google’s Site Reliability Engineering book, chapter 6.
Where: at the edge, where users meet the service.
No Credit Card Required
Printed from checkflow.io/templates/information-technology/monitoring-alerting-setup-checklist
This free monitoring and alerting checklist brings a service under monitoring properly, then keeps it that way. Operations teams, SREs and MSPs use it when a service goes live and every quarter after. It covers the inventory of what to watch, golden signals, SLOs and burn-rate alerts, severity and routing to the on-call rotation, a runbook for every page, a test that proves each page arrives, and a review that removes the alerts nobody acts on.
Three well-known methods tell you what to measure. They overlap but answer different questions: is the service working for users, is each component healthy, and is each resource running out. A well-monitored service uses all three.
Measures: latency, traffic, errors and saturation.
Source: Google’s Site Reliability Engineering book, chapter 6.
Where: at the edge, where users meet the service.
Measures: rate, errors and duration of requests.
Source: Tom Wilkie, then at Weaveworks, for microservices.
Where: every API, endpoint and queue consumer.
Measures: utilisation, saturation and errors.
Source: Brendan Gregg’s performance methodology.
Where: CPU, memory, disk, network and connection pools.
Measuring is not the same as alerting. The SRE book separates symptoms (what is broken: users get errors or slow pages) from causes (why: a database refusing connections, a CPU at its limit). It says every page should be actionable, and that cause-based pages should be kept for causes that are definite and imminent. This checklist applies that rule: golden signals and SLOs drive pages; most RED and USE metrics feed dashboards and tickets. Writing the runbook behind each page is covered in more depth in our guide to writing an IT runbook.
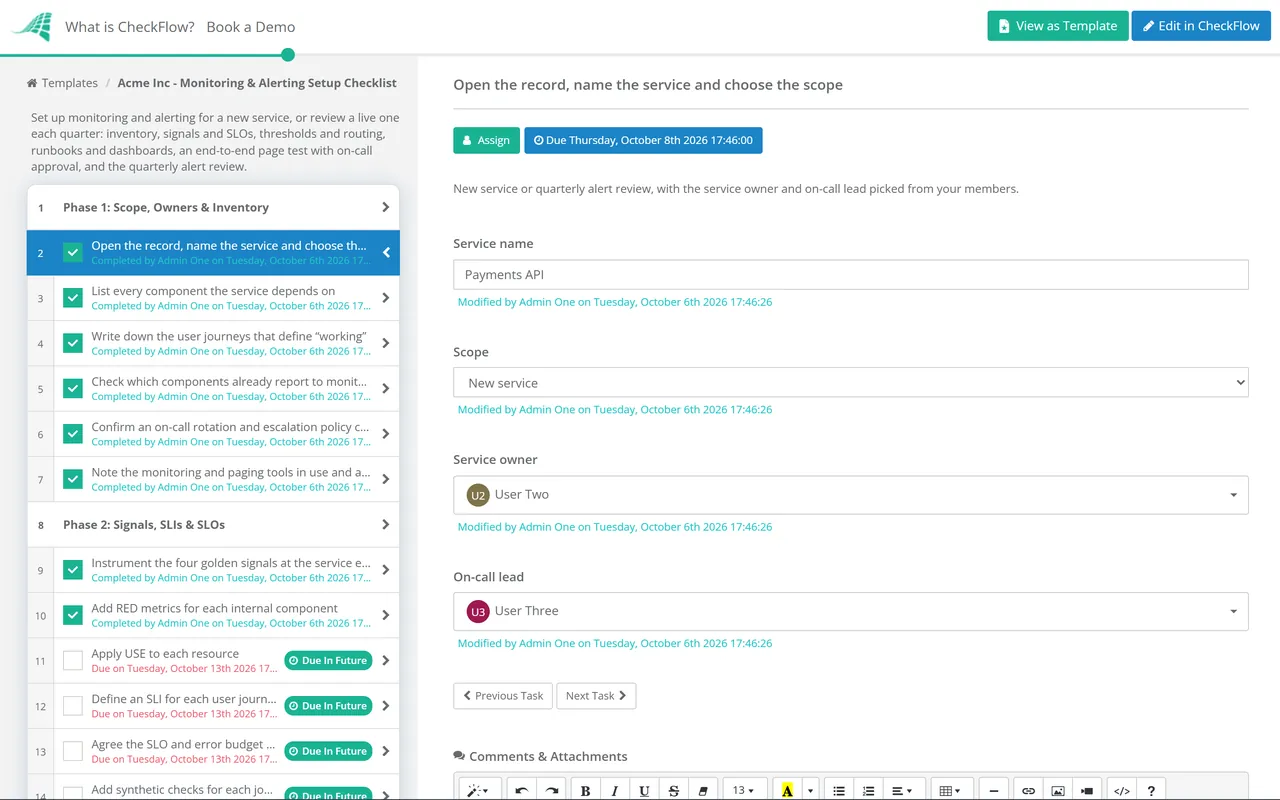
Seven phases take a service from inventory to a tested, reviewed alert set. Phases 2 to 4 appear for a new service, Phase 6 for the quarterly alert review, and a failed end-to-end test adds a fix task before go-live is approved.
The scope answer on the first task decides whether the build phases or the review phase appear.
Tasks appear only when the scope is a new service.
Tasks appear only when the scope is a new service. The alert table lives in this phase.
for: 5m clause in Prometheus, or the equivalent elsewhere, so one spike does not wake anyoneTasks appear only when the scope is a new service.
A Fail result shows the fix task. The on-call lead’s approval on the last task halts the checklist until they decide.
promtool check rules, amtool check-config, and amtool config routes test with each alert’s labelsTasks appear only when the scope is the quarterly alert review.
Phase 3 records every alert as one row, and Phase 6 reviews the same table each quarter. These example rows are for a web shop’s checkout service. The thresholds are common starting points, not rules; tune them to your own SLOs and traffic.
| Alert | Condition | Severity | Route | Runbook |
|---|---|---|---|---|
| Checkout errors, fast burn | Error budget burning at 14.4× over 1 hour and over the last 5 minutes | Page | Primary on-call, then secondary if not acknowledged | Checkout errors |
| Checkout errors, slow burn | Burning at 6× over 6 hours and over the last 30 minutes | Page | Primary on-call | Checkout errors |
| Checkout budget drift | Burning at 1× over 3 days and over the last 6 hours | Ticket | Team queue | SLO review |
| Sign-in journey failing | Synthetic check failing from 2 of 3 locations for 5 minutes | Page | Primary on-call | Sign-in failures |
| Database disk filling | Predicted to fill within 4 hours at the current rate | Page | Primary on-call | Disk space |
| Certificate expiring | Fewer than 14 days to expiry on any endpoint | Ticket | Platform team queue | Certificate renewal |
| Watchdog | Always firing | Heartbeat | External heartbeat service | Monitoring pipeline down |
The burn-rate rows come from the SRE Workbook’s chapter on alerting on SLOs. A 14.4× burn sustained for an hour uses 2% of a 30-day error budget; requiring the short window as well means the alert clears soon after the problem stops. Azure Monitor offers five severities (Sev 0 Critical to Sev 4 Verbose); if two levels lead to the same response, merge them.
Prometheus Alertmanager waits 30 seconds by default before the first notification for a group, 5 minutes before telling you about new alerts in that group, and 4 hours before repeating one still firing. Escalation when nobody acknowledges belongs in the paging tool’s escalation policy. If that tool is Opsgenie, note that Atlassian ended new sales on 4 June 2025 and switches the product off on 5 April 2027; the move to Jira Service Management or Compass is a routing change, and Phase 5’s tests apply to it in full.
One scope answer shows the build phases for a new service or the review phase for an existing one. A quarterly recurring schedule opens the alert review for each service, assigned to its owner with a due date, so pruning noise does not wait for the next bad week on call.
The alert table inside the routing task holds every alert’s threshold, severity, route and runbook, and the next review starts from it. A data set can hold your services with owner and rotation, and tags keep each client’s estate separate for MSPs.
The end-to-end test result is a required dropdown: record Fail and the fix task appears. The on-call lead’s approval halts the checklist until they decide, and the audit trail shows who tested which route and when, with screenshots attached to the task.
Alerts feed the people who answer them. Pass changed and silenced alerts across at each rotation change with the On-Call Handover Checklist, run the response through the Incident Management Process Checklist, and feed incidents no alert caught back into Phase 6 from the Incident Postmortem Template.
Certificate expiry is one of the alerts most teams add after an outage; the SSL/TLS Certificate Renewal Checklist covers the renewal behind it. To see how quarterly reviews run on a schedule without anyone remembering to start them, read about CheckFlow’s recurring checklist software.
On-Call Handover Checklist
Incident Management Process Template
Incident Postmortem Template
IT Capacity Planning Checklist
Problem Management Checklist
Describe the process in a sentence and the AI checklist generator drafts the phases and tasks for you.
Latency, traffic, errors and saturation. They come from the “Monitoring Distributed Systems” chapter of Google’s Site Reliability Engineering book, which advises that if you can measure only four metrics of a user-facing system, these are the four. Track latency as percentiles, and separately for failed requests: a fast error can make latency look healthy while users are failing.
All three, at different layers. Golden signals describe the service as users experience it. RED (rate, errors, duration) applies the same idea to every request-driven component inside it. USE (utilisation, saturation, errors) checks each resource such as CPU, disk and connection pools. Page on the first; use RED and USE mainly to diagnose, on dashboards and in tickets.
An alert on how fast a service is spending its error budget. A burn rate of 1 uses the whole budget in exactly the SLO period; 14.4 sustained for an hour uses 2% of a 30-day budget. The SRE Workbook recommends checking a long and a short window together, which catches real problems quickly and stops alerting soon after they end, with fewer false pages than a fixed error threshold.
Google’s SRE book sets a maximum of two incidents per 12-hour shift, because handling one properly, from diagnosis to postmortem and follow-up fixes, takes about six hours. Your target may differ, but count pages per shift at every quarterly review. When the number climbs, the fix is usually to delete or demote alerts, not to add people to the rotation.
In three layers. Check configuration before it ships, with promtool for rules and amtool config routes test for routing. Then fire each paging alert once in a controlled way and confirm it reaches the right phone and resolves. Finally, run a watchdog alert that always fires to an external heartbeat service, so a broken monitoring pipeline raises its own alarm instead of going quiet.
14-day free trial, no card required. The Business plan is $10 per user per month after the trial. Full details at checkflow.io/pricing.
14-day free trial, no credit cardFull refund in your first 30 daysUS hosting, EU on request