
Can this backup be restored?
Scope: a rotating sample of systems restored into an isolated network.
Cadence: monthly.
Last reviewed: October 2026
No Credit Card Required
Printed from checkflow.io/templates/information-technology/disaster-recovery-test-checklist
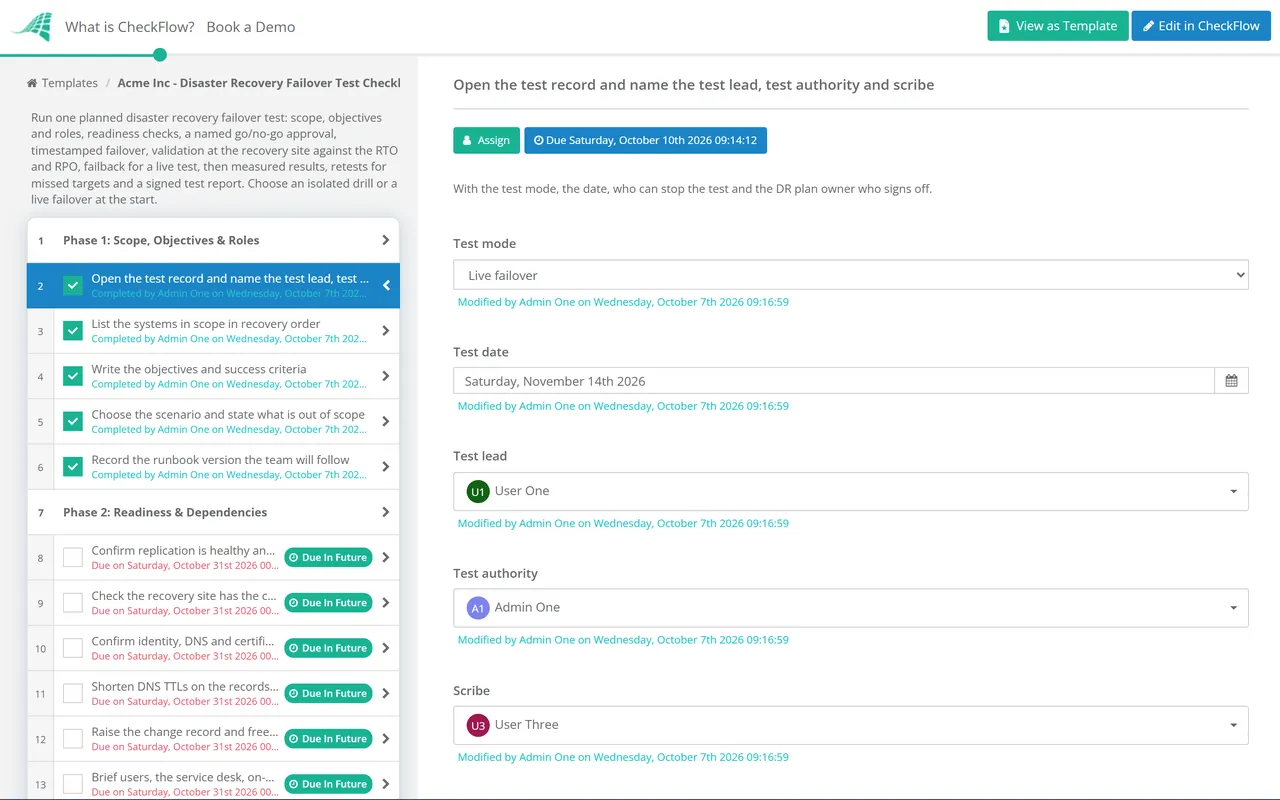
This free disaster recovery test checklist is the runbook for one planned test, used by infrastructure leads, DR coordinators and MSPs testing on a client’s behalf. It takes the test from objectives and a go/no-go decision through failover, validation and failback, then measures real recovery time and data loss against each system’s targets. It covers a live failover and an isolated drill that leaves production running. The output is a timestamped test record, an issues log, updated runbooks and a signed report.
NIST SP 800-34 Rev. 1, the US government’s contingency planning guide, separates tests, which use measurable results to prove a system works, from exercises, which simulate an emergency. For high-impact systems it expects a full-scale functional exercise that includes failover to the alternate location and a full recovery and reconstitution to a known state. That is the event this checklist runs.
AWS Elastic Disaster Recovery draws a useful line too. It calls a non-disruptive test a drill, and treats failover, redirecting production traffic to the recovery instances, as a step you perform outside the service. Recovering machines and moving users are separate jobs, and the test mode chosen on the first task decides which of them this run covers.
Scope: a rotating sample of systems restored into an isolated network.
Cadence: monthly.
Scope: the systems in one recovery plan, failed over in order, used, then failed back.
Cadence: as the DR test programme sets, often yearly per critical system.
Use: this checklist.
Scope: plan, backups, recovery site, communications and compliance.
Cadence: annually, using test records as evidence.
Use: the Disaster Recovery Audit Checklist.
If nothing is switched over and the team talks the scenario through, it is a tabletop, not a failover test. Business tabletops and functional exercises run through the Business Continuity Plan Testing Checklist, which leaves the IT recovery test to IT operations. This page is that test.
Seven phases take one test from objectives to a signed report. The test mode decides which failover and failback tasks appear, the test authority approves the go/no-go before anything moves, and the DR plan owner signs off the result. There is no fixed schedule: open one record per test from your DR test programme.
The test mode recorded on the first task, Isolated drill or Live failover, decides which tasks appear in Phases 2, 4, 5 and 6.
The DNS task appears only for a live failover.
The test authority named in Phase 1 records Approved or Not approved on the last task. The checklist halts there, and nothing fails over until they decide.
Stopping writes at the primary and redirecting users appear only for a live failover. In a drill, production keeps running.
Application owners picked in Phase 1 run their own checks. The isolation check appears only for a drill.
The first three tasks appear only for a live failover. Every test ends with replication healthy and the temporary resources gone.
Answering No to “All targets met?” adds the retest task. The DR plan owner signs off the report, and the checklist halts until they record a decision.
A recovery time worked out afterwards from memory is always flattering. The scribe logs these points as they happen, and the results in Phase 7 are simple subtraction.
| Timestamp | Logged when | Used for |
|---|---|---|
| Declared start | The test lead starts the clock in Phase 4 | The zero point for every recovery time |
| Last write at the primary | Writes stop, or the reference point in a drill | The start of the data loss window |
| Newest recovered record | Checked at the recovery site in Phase 5 | Data loss: last write minus newest recovered record, against RPO |
| System declared recovered | Its application owner can use it | Recovery time: this minus declared start, against RTO |
| Users redirected | DNS and load balancers point at the recovery site | How long users waited after the system was ready |
| Normal operations resumed | Failback complete, users back on the primary | The total disruption the test caused |
An isolated drill brings the recovery copies up on a separate network while production carries on. Microsoft describes an Azure Site Recovery test failover as a drill that does not affect ongoing replication or production, and recommends an isolated test network. If a drill runs in the production network instead, shut the primary down first: two machines with the same identity on one network cause unexpected results.
A drill measures how quickly systems come up and how current their data is. It cannot measure user redirection, real load at the recovery site or failback. A common pattern is drills through the year and one live failover and failback per critical system each year, but NIST leaves the frequency organisation-defined.
The activity trail records who completed each step and when, so the failover timeline comes from the record, not from the scribe’s notes. A table inside the systems task holds each system’s targets and measured results, and comments capture decisions made under pressure.
The go/no-go goes to the test authority picked on the first task, and the checklist halts until they record Approved or Not approved. Conditional logic shows the live failover and failback tasks only when the test mode calls for them, and the drill isolation check only for a drill.
Each issue is assigned to a person or group with a due date. Validation screenshots and the report attach as audit evidence, and template versioning keeps a history as the runbook improves after each test.
Our disaster recovery checklist guide covers the programme around this test: setting RTO and RPO, the business impact analysis and the range of test types. The annual Disaster Recovery Audit Checklist uses this checklist’s signed reports as its evidence that failover was tested.
If something real breaks during the test, hand over to the Incident Management Checklist. Rehearsing ransomware decisions with no systems moved is the job of the Incident Response Tabletop Exercise Template.
Disaster Recovery Audit Checklist
Business Continuity Plan Testing Checklist
Backup Verification & Restore Test Checklist
Incident Response Tabletop Exercise Template
Incident Postmortem Template
Describe the process in a sentence and the AI checklist generator drafts the phases and tasks for you.
It is a planned event in which systems are recovered at the secondary site or cloud region, used there for a period, and then returned to the primary. Unlike a single restore test, it exercises the whole recovery plan, and it measures real recovery time and data loss against the targets the business was promised.
Failover moves the service from the primary site to the recovery site. Failback brings it home again, which means replicating every change made at the recovery site back to the primary before users switch over. It is rehearsed less than failover, so treat it as a second change with its own window and go decision.
Log timestamps as the test runs. Measured recovery time is the time a system was declared usable by its owner minus the declared start of the test, compared with its RTO. Data loss is the time of the last write at the primary minus the time of the newest record found at the recovery site, compared with its RPO. Note the last transaction number beforehand so the comparison is exact.
Yes, with an isolated drill. Tools such as Azure Site Recovery and AWS Elastic Disaster Recovery can bring up recovery copies while replication and production carry on, ideally on a network that cannot reach production. A drill does not prove user redirection or failback, so the most critical systems still need a live failover from time to time.
Yes. Revision 1, last updated in November 2010, is still the version NIST lists as final in October 2026, and no Revision 2 has been published. It ties the depth of testing to a system’s impact level: a tabletop for low-impact systems, a functional exercise with recovery from backup for moderate, and a full-scale functional exercise with failover to the alternate site for high-impact systems.
14-day free trial, no card required. The Business plan is $10 per user per month after the trial. Full details at checkflow.io/pricing.
14-day free trial, no credit cardFull refund in your first 30 daysUS hosting, EU on request